A nine-step playbook to improve AI search visibility through prompt mapping, citable evidence, entity consistency, source authority, technical access, and outcome measurement.
Explore 12,000+ niche markets with no login required
AI search visibility is not a single ranking. It is the probability that systems such as ChatGPT, Google AI Overviews and AI Mode, Perplexity, Gemini, Claude, and Copilot will recognize your brand, describe it accurately, and use credible pages as evidence when buyers ask relevant questions.
Improving that probability requires more than adding keywords. You need to understand the prompts that matter, publish facts that machines can retrieve and verify, earn corroboration from trusted third parties, and measure whether mentions and citations lead to business outcomes. This guide provides a practical nine-step operating system for doing that.
What “brand visibility” in AI search actually means
Measure four signals separately:
Mention rate: the percentage of tracked answers that name your brand.
Citation rate: the percentage that cite your domain or a page about you.
Recommendation rate: how often the brand is presented as a suitable option, not merely mentioned.
Narrative accuracy: whether descriptions of price, audience, capabilities, locations, and differentiators are correct.
A citation without a recommendation can still create discovery. A recommendation based on wrong product facts can damage conversion. A high mention rate across irrelevant prompts is less valuable than a lower rate on high-intent comparison and purchase questions. Always retain the raw answer behind an aggregate score.
The nine-step AI visibility playbook
1. Build a buyer-prompt map, not a keyword dump
Start with decisions customers make. For each product or service, map prompts into six groups:
Prompt group
Example
What success means
Problem discovery
“How do I measure brand mentions in ChatGPT?”
Your educational content is cited
Category
“Best AI visibility platforms”
Your brand enters the consideration set
Use case
“AI search monitoring for SaaS teams”
The answer connects you to a real audience
Comparison
“Dageno vs [competitor]”
Differences are accurate and evidenced
Objection
“Affordable GEO tools with citation tracking”
Limitations and value are represented fairly
Validation
“Is Dageno reliable?”
Trusted third-party evidence supports the claim
Include exact buyer language from sales calls, support tickets, community discussions, site search, GSC queries, and competitor pages. Group near-duplicates so that the measurement set represents demand instead of inflating it with trivial wording variations.
Begin with 30–50 prompts per market. Assign an intent, funnel stage, product, audience, country, and language to every prompt. This makes later analysis actionable: a lost enterprise comparison prompt should trigger a different response than a lost beginner definition prompt.
2. Establish a repeatable baseline
Run the same prompt set across the engines and markets that influence your buyers. Record the date, model or surface, region, language, raw answer, brand position, cited URLs, competitors, and sentiment.
Do not treat one response as a ranking. AI answers vary because retrieval, model versions, query fan-out, location, and sampling vary. Use repeated observations and report a rolling rate. Keep prompt wording and configuration stable during the baseline period; otherwise you cannot tell whether the brand improved or the experiment changed.
A useful baseline dashboard separates:
commercial prompts from informational prompts;
mentions from owned-domain citations;
brand visibility from competitor share of voice;
overall trends from engine-, market-, and language-level trends;
visibility from referral traffic, assisted conversions, and qualified pipeline.
3. Diagnose the gap before creating content
For every important prompt where a competitor wins, classify the reason:
Coverage gap: you do not have a page that directly answers the question.
Evidence gap: the page exists but lacks original data, examples, methodology, or references.
Authority gap: third-party sources discuss competitors but rarely mention you.
Entity gap: product facts are inconsistent across your site, profiles, listings, and reviews.
Retrieval gap: key information is hidden, blocked, script-dependent, fragmented, or difficult to crawl.
Freshness gap: pricing, features, screenshots, and dates no longer match the product.
Experience gap: the article repeats generic advice without showing real tests or decisions.
This diagnosis prevents a common failure: publishing ten more articles when the actual problem is inconsistent product data or weak external corroboration.
4. Make your brand and product facts unambiguous
Create one canonical source of truth for the facts an answer engine may need: official brand name, category, target customer, primary use cases, feature definitions, supported markets, pricing model, founders or company details, contact information, and last-updated date.
Then reconcile high-authority public surfaces—homepage, product pages, About page, documentation, pricing, organization profiles, marketplaces, and major review platforms. The goal is consistency, not repetition. If one page says the product supports seven engines and another says nine, an AI system has to resolve the conflict.
Use structured data only when it matches visible content. Organization, Product, SoftwareApplication, Article, BreadcrumbList, and FAQPage markup can clarify relationships, but markup cannot rescue vague or unsupported copy. Keep author, publisher, dates, product names, and canonical URLs aligned.
5. Publish pages that deserve to be cited
AI systems often need a compact passage that answers a specific question and a reason to trust it. Build each important page around both.
A strong source page usually includes:
a direct answer near the relevant heading;
explicit scope, definitions, and limitations;
a comparison table with consistent evaluation criteria;
original screenshots, workflows, examples, or data;
a methodology and observation date for research claims;
named authors or reviewers with relevant experience;
clear links to supporting primary sources;
a visible update history when facts materially change.
For commercial topics, explain who the product is for, who should not choose it, the setup required, the evidence available, and what a buyer should test. This is more useful—and more citable—than describing every tool as “powerful” or “all-in-one.”
Owned content defines your position; third-party sources help validate it. Identify the domains that appear repeatedly in answers for your prompt clusters. Prioritize relevant industry publications, professional communities, comparison sites, review platforms, directories, partners, customers, and expert contributors—not a generic backlink list.
Create evidence that gives those sources a reason to mention you: transparent benchmarks, original datasets, expert commentary, integrations, customer outcomes with methodology, and genuinely useful free tools. When doing outreach, match the asset to the publication’s audience and disclose commercial relationships.
Measure earned visibility by source quality and prompt relevance. A mention on a trusted niche page that repeatedly informs purchase answers can matter more than dozens of unrelated links.
7. Remove retrieval and internal-discovery friction
Make important facts available in server-rendered text and keep navigation paths short. Check status codes, canonical tags, robots directives, XML sitemaps, JavaScript rendering, duplicate variants, and accidental paywalls or login gates. Review access rules for the search and AI agents your organization has chosen to permit.
Internal links should describe the destination and connect a topic as a coherent system. Link definition pages to measurement guides, measurement guides to implementation playbooks, and comparison pages to first-party product evidence. Avoid orphan pages and repetitive exact-match anchors across every article.
8. Turn monitoring evidence into a weekly action queue
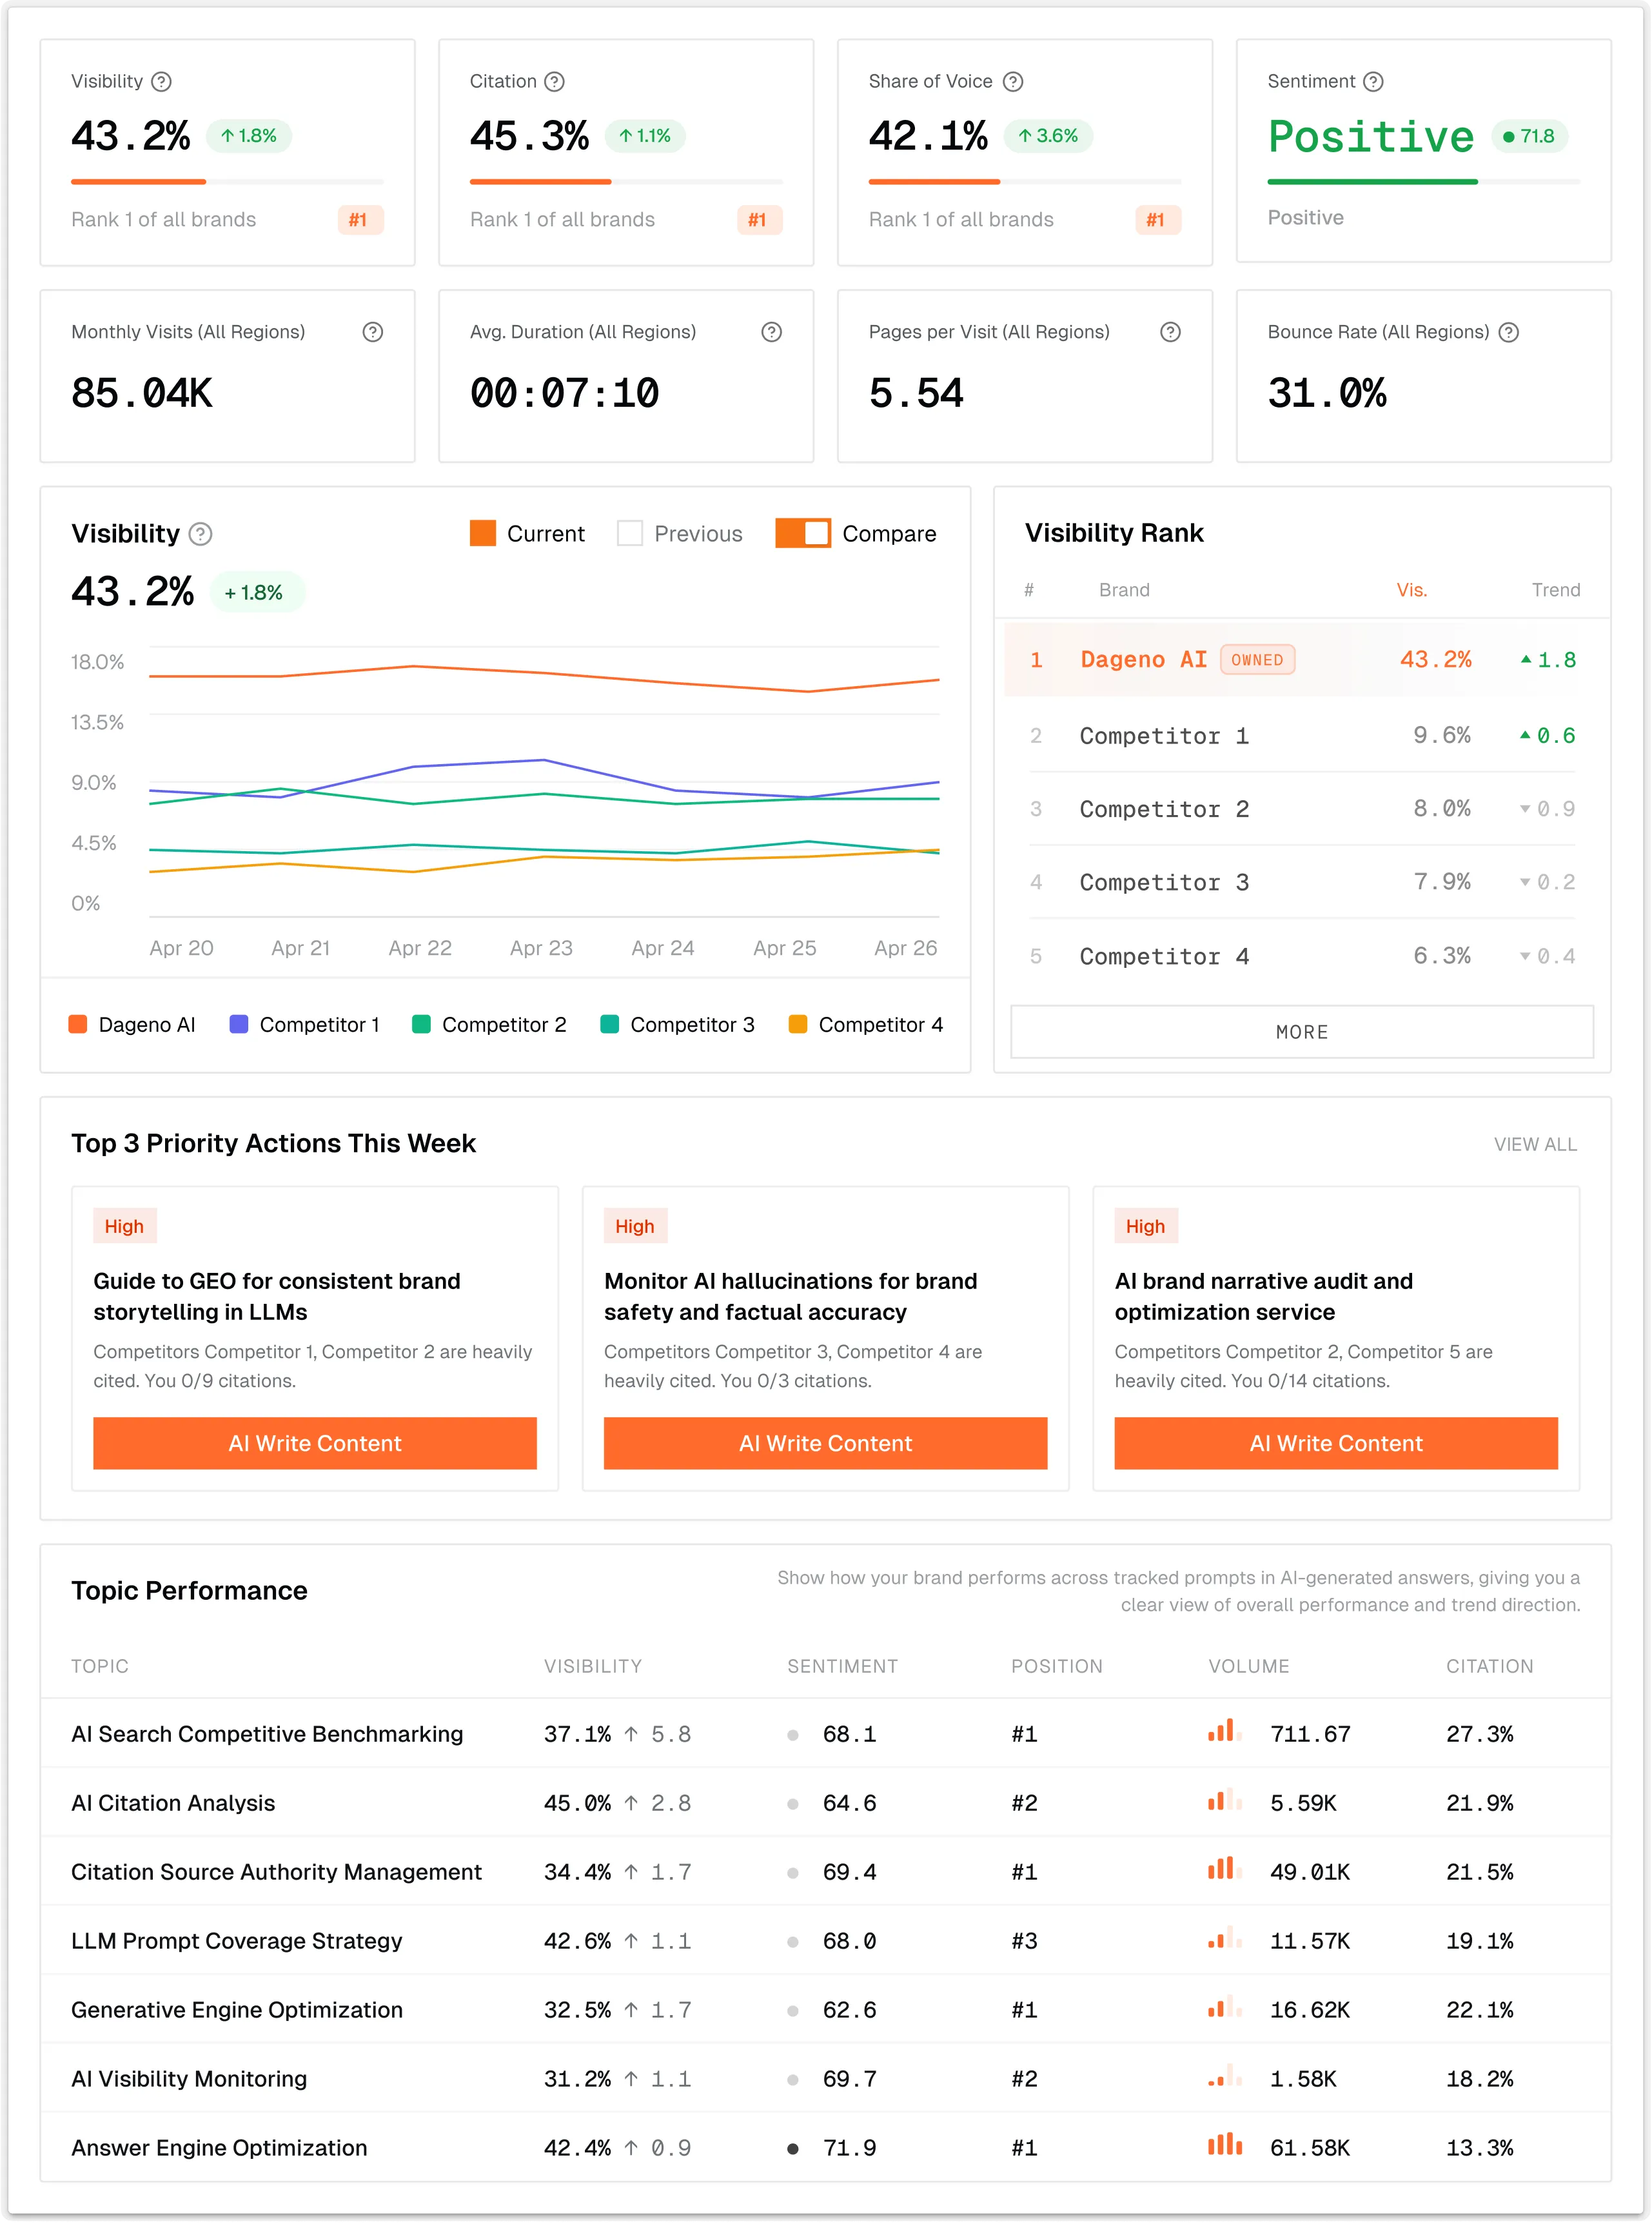
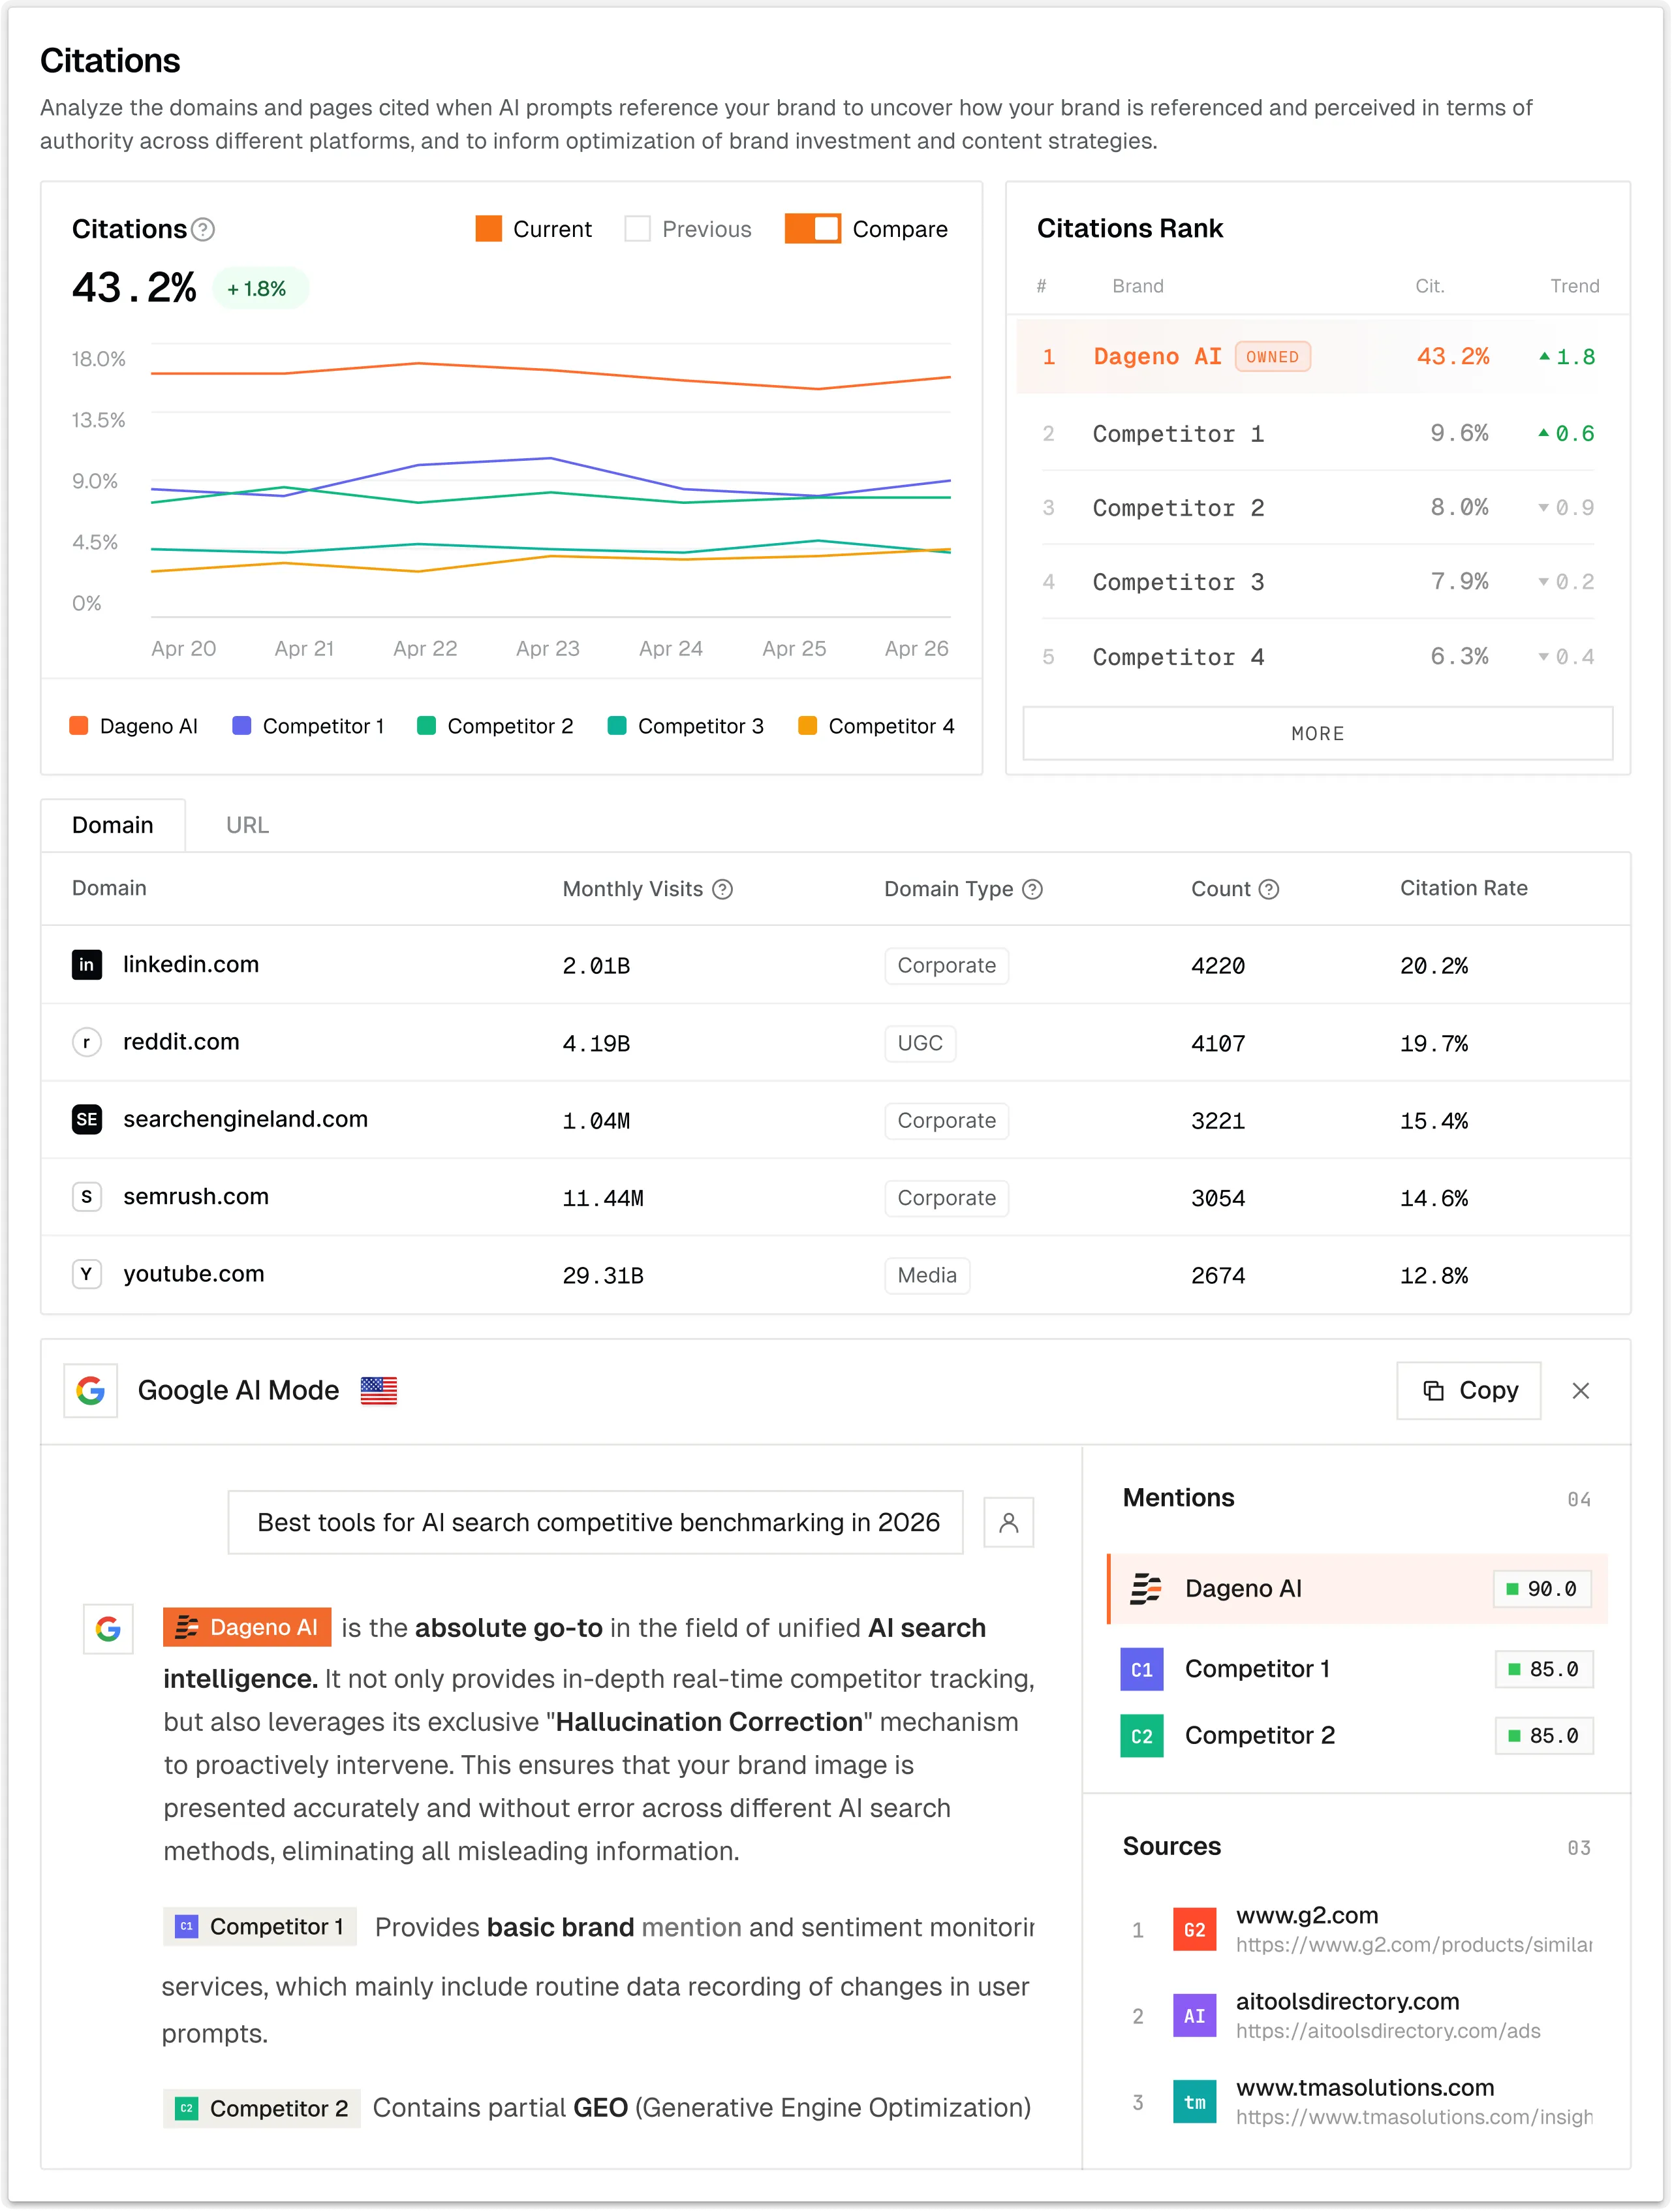
Dageno can connect prompt-level visibility, citations, competitor gaps, and crawler evidence so teams can move from “visibility changed” to a testable action.
Use the workflow this way:
Filter lost or missing prompts by commercial value.
Open the raw answers and cited URLs.
Compare the winning source’s evidence, format, freshness, and authority with your page.
Assign the gap to content, technical SEO, entity data, product, digital PR, or partnerships.
Record the change and recheck the same prompt cohort over several runs.
Answer Engine Insights supports prompt, competitor, and citation analysis, while BotSight Analytics helps distinguish crawler access from actual answer visibility. That distinction matters: bot activity proves access, not recommendation.
9. Validate changes against outcomes, not vanity scores
Tag every material change with the affected URL, prompt cohort, date, hypothesis, and owner. Compare a stable pre- and post-change window, while noting product launches, PR campaigns, engine changes, and prompt-set edits.
Use a measurement ladder:
Level
Metric
Decision it supports
Retrieval
crawler access, indexed page, cited passage
Can systems reach and use the evidence?
Visibility
mention, citation, recommendation, share of voice
Did answer presence change?
Perception
sentiment and fact accuracy
Is the brand represented correctly?
Engagement
AI referral visits and engaged sessions
Are visible answers sending useful visitors?
Business
sign-ups, assisted conversions, pipeline
Is the program creating commercial value?
Do not claim causation from a single before-and-after screenshot. Look for consistent movement across the targeted prompt cohort and downstream behavior.
A practical 30-60-90 day plan
Days 1–30: measure and repair
define the prompt taxonomy and priority markets;
capture a repeatable baseline;
reconcile brand and product facts;
fix blocking, canonical, rendering, and orphan-page issues;
select the 10 highest-value visibility gaps.
Days 31–60: build evidence
upgrade or consolidate pages for the priority gaps;
add first-party examples, screenshots, comparisons, and methodology;
improve internal links between supporting pages and commercial pages;
approach the third-party sources that already influence the relevant answers;
monitor the unchanged prompt cohort weekly.
Days 61–90: validate and scale
compare visibility, narrative accuracy, referrals, and conversions;
keep winning formats and retire low-value duplicate work;
expand into the next language or market only after localizing prompts and evidence;
assign recurring owners for content, technical access, entity data, and digital PR.
Mistakes that suppress AI brand visibility
Tracking only branded prompts, which measures recognition rather than discovery.
Treating a mention, citation, recommendation, and referral as the same outcome.
Publishing near-duplicate “best tools” pages that compete with one another.
Making unsupported superlatives or invented pricing claims.
Updating the date without rechecking product facts and screenshots.
Translating keywords literally without researching local buyer language and sources.
Blocking retrieval while assuming schema alone will expose the content.
Reacting to one volatile answer instead of a repeatable cohort trend.
Frequently asked questions
How long does it take to improve visibility in AI search?
Technical and entity corrections can be reflected relatively quickly, while new authority and repeated source selection usually take longer. Evaluate trends across several runs and weeks, not one answer. The time depends on crawl frequency, source freshness, competition, and the strength of the evidence created.
Is traditional SEO still important for AI visibility?
Yes. Crawlability, useful content, internal links, authority, and strong source pages still matter. AI visibility adds new measurement units—prompts, answers, mentions, citations, and narrative accuracy—rather than eliminating search fundamentals.
Should every page be optimized for AI search?
No. Prioritize pages that answer high-value buyer questions or provide authoritative product facts and evidence. Consolidate thin overlap instead of optimizing every URL independently.
What is the most useful weekly report?
Report changes in high-value prompt cohorts, the raw answers behind them, newly gained or lost citations, inaccurate claims, competitor source gains, actions completed, and any movement in qualified referrals or conversions. Every chart should lead to an owner and next action.
Final checklist
AI visibility improves when a brand becomes easy to identify, easy to retrieve, and safe to cite. Build a representative prompt map, preserve raw evidence, resolve entity conflicts, publish genuinely referenceable pages, earn relevant external corroboration, and validate changes against business outcomes. That operating discipline is more durable than chasing a single model response.
Tim is the co-founder of Dageno and a serial AI SaaS entrepreneur, focused on data-driven growth systems. He has led multiple AI SaaS products from early concept to production, with hands-on experience across product strategy, data pipelines, and AI-powered search optimization. At Dageno, Tim works on building practical GEO and AI visibility solutions that help brands understand how generative models retrieve, rank, and cite information across modern search and discovery platforms.