How to Find Brand Mentions in AI Search: A Starter Guide
Build a reliable AI brand mention monitoring baseline with a controlled prompt set, repeatable sampling, citations, competitor share of voice, accuracy checks, and a 30-day workflow.
Explore 12,000+ niche markets with no login required
Finding one flattering ChatGPT answer is not AI search monitoring. A useful monitoring program repeatedly tests the questions buyers ask, records whether the brand appears, captures the sources behind the answer and compares the result with competitors over time.
This guide gives a new team a practical starting system that can be run manually before it invests in automation.
What counts as an AI brand mention?
A brand mention occurs when an AI-generated answer names the company, product or an accepted brand variation in the answer text. Keep it separate from related signals:
Signal
What it means
Example
Mention
The answer names the brand
“Dageno is an AI visibility platform”
Recommendation
The brand is suggested for the user’s need
“Consider Dageno for citation tracking”
Citation
The answer links to or attributes information to a source
A Dageno page appears in the sources
Position
The brand’s order in a comparison or list
The brand is the second named option
Sentiment
How the answer characterizes the brand
Positive, neutral, negative or mixed
Accuracy
Whether material claims are correct
Pricing, integrations and product scope match current facts
A company can be cited without being recommended, mentioned without receiving a link, or recommended using an inaccurate claim. Reporting only “visibility” hides these differences.
Step 1: Define the brands and entities to track
Create a small entity dictionary before writing prompts. Include the official company name, product names, common abbreviations, previous names, domain and common misspellings. Add explicit exclusions for ambiguous names.
For every competitor, record the same fields. This prevents a simple text matcher from counting an unrelated word as a brand mention or missing a shortened product name.
Set an accuracy policy
Decide which claims are material enough to review: category, price, availability, location, security certification, integrations and target customer. Give every material claim a status—correct, outdated, unsupported or contradictory.
Step 2: Build a representative prompt portfolio
Do not start with only branded prompts such as “What is Acme?” Those test existing awareness, not discovery. Build 50–100 questions across real buying stages.
Use five prompt groups
Category discovery: “What are the best tools for monitoring AI citations?”
Problem and use case: “How can a SaaS company find missing brand mentions in ChatGPT?”
Comparison: “Tool A vs Tool B for multilingual tracking.”
Constraint: “Affordable AI visibility tools for a three-person marketing team.”
Trust and validation: “Which platforms publish source-level evidence?”
Tag every prompt by persona, product, funnel stage, country and language. Keep the exact wording stable for trend analysis, while maintaining a separate set of natural-language variants for robustness testing.
Step 3: Choose the AI surfaces and test conditions
Select the engines your buyers actually use. A practical baseline can include ChatGPT, Google AI experiences, Gemini, Perplexity, Claude, Copilot and Grok, but coverage should follow audience evidence rather than a generic checklist.
Record the model or product surface, date, account state, country, language and whether web search was enabled. Personalized and non-personalized experiences can return different answers. Never compare results collected under undocumented conditions.
Step 4: Run a manual baseline
For the first baseline, run each prompt and store the complete answer—not only a screenshot. Capture:
Exact prompt and timestamp.
Answer text and brand position.
Named competitors.
Citation URLs and domains.
Sentiment and material factual claims.
Whether a link points to the brand, a third party or no source.
Repeat a subset of prompts two or three times. Generative answers vary, so one run is an observation, not a durable ranking.
Step 5: Calculate metrics that lead to action
Mention rate
Answers mentioning the brand ÷ valid answers tested
Calculate this by topic and funnel stage. An overall average can hide weak commercial prompts.
Share of voice
Brand mentions ÷ mentions of all tracked brands
Define whether multiple mentions in one answer count once or several times and keep that rule consistent.
Citation rate
Track both brand-domain citation rate and third-party citation distribution. The first measures owned-source visibility; the second shows which publications, communities and comparison pages influence answers.
Recommendation and accuracy rates
A recommendation is more commercially meaningful than an incidental mention. Accuracy is a separate risk metric: frequent but incorrect visibility can damage trust.
Step 6: Turn the baseline into a gap map
Every missed prompt should be assigned a likely gap:
Entity gap: the engine does not connect the product with the category.
Content gap: the site does not answer the question directly.
Evidence gap: claims lack first-party data, examples or methodology.
Technical gap: important pages are blocked, difficult to render or poorly structured.
Freshness gap: critical product facts are inconsistent across pages and profiles.
Do not publish a new article for every missed prompt. Improve an existing authoritative page when the intent already belongs there; create a new page only when it serves a distinct user need.
Use Dageno to automate the monitoring workflow
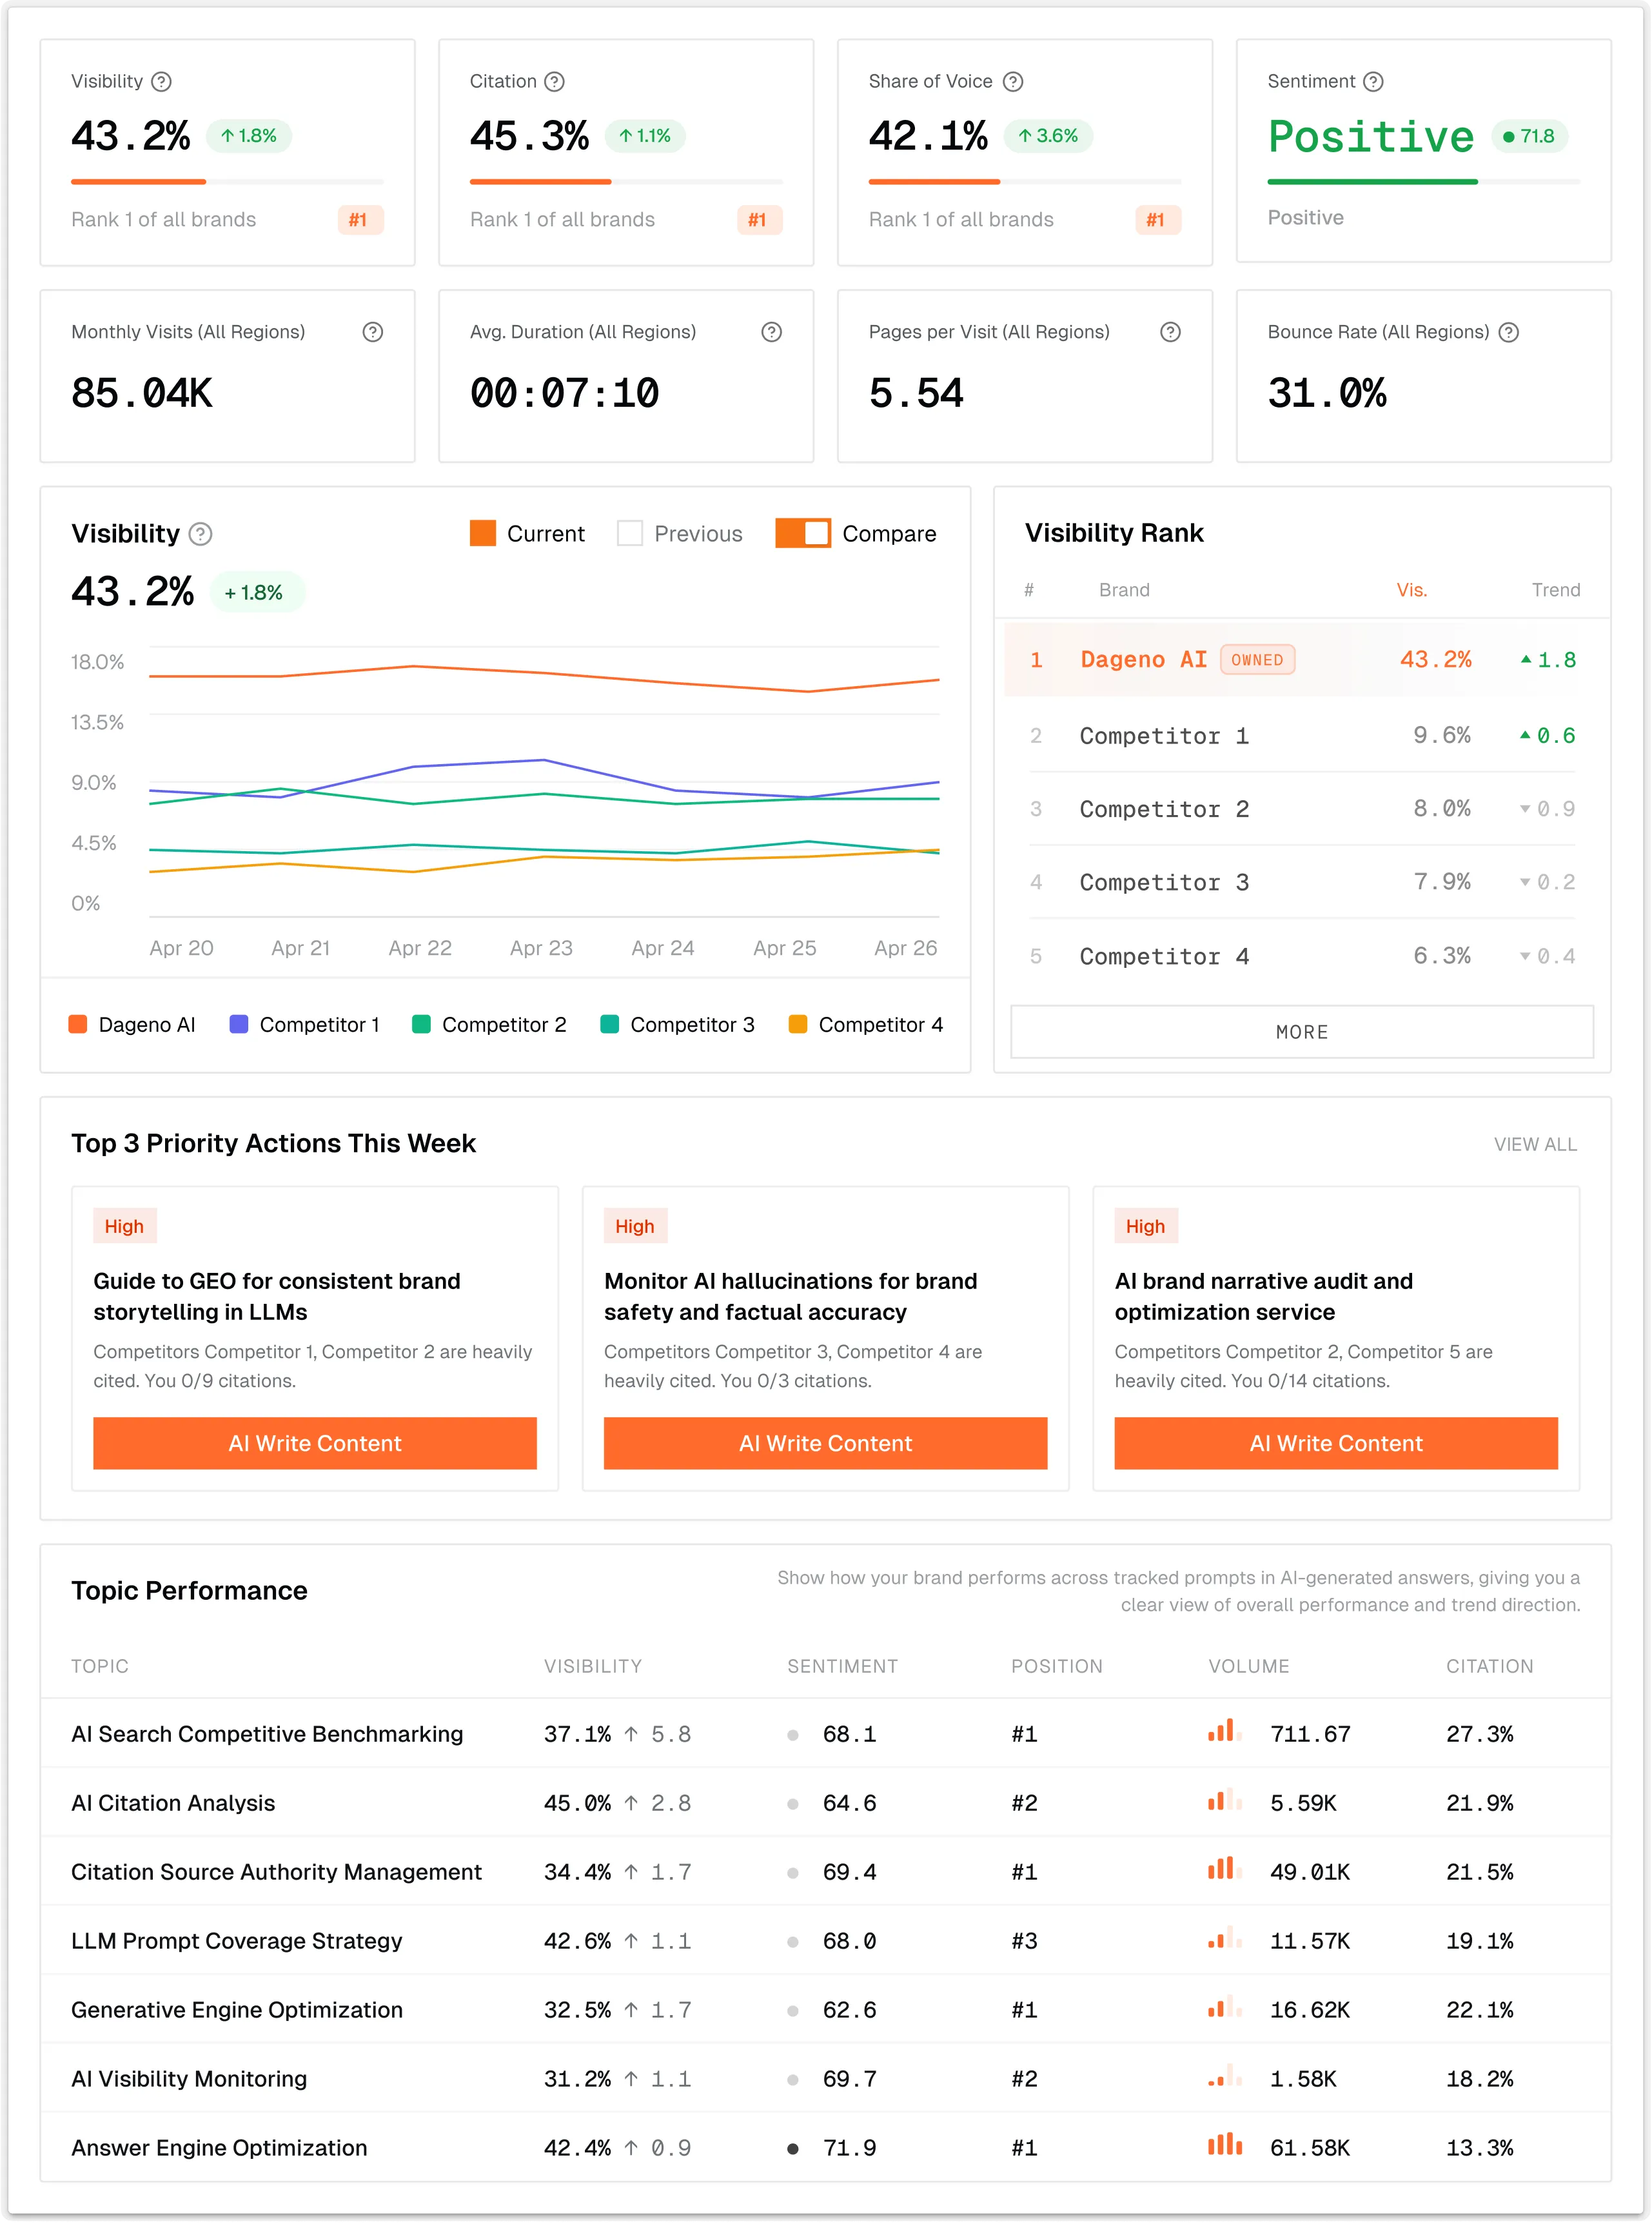
Dageno helps teams replace manual sampling with repeatable prompt, competitor and citation monitoring. It preserves the evidence behind the metric, allowing a marketer to move from “visibility fell” to the questions, competitors and sources responsible for the change.
A practical Dageno workflow
Import the approved prompt portfolio and entity variations.
Group prompts by market, persona, product and funnel stage.
Establish mention, recommendation, citation and competitor baselines.
Review source domains and content gaps for lost prompts.
Prioritize a small set of interventions and record deployment dates.
Rerun the same portfolio and compare trends with a control group.
Each week, identify newly won and lost prompts, changed recommendations, new citation domains and material inaccuracies. Assign an owner and deadline only when the evidence suggests a useful intervention.
Separate visibility from traffic and revenue
AI mentions can influence discovery without producing a directly attributable click. Use analytics, Search Console, branded search and self-reported attribution as complementary signals. Do not claim revenue from a mention unless the measurement supports it.
Keep a change log
Record content updates, technical fixes, digital PR placements, product launches and major profile changes. Without a change log, a trend chart cannot explain what the team did.
Common mistakes to avoid
Tracking only the brand name instead of non-branded buying questions.
Changing prompts every week and calling the result a trend.
Treating mention, citation, recommendation and sentiment as one metric.
Comparing tools with different engines, countries or sampling frequency.
Publishing generic content for every gap.
Ignoring inaccurate positive mentions.
Reporting a single generated answer as a stable rank.
A 30-day starter plan
In week one, define entities, competitors and 50–100 prompts. In week two, run a manual baseline and classify gaps. In week three, make three controlled interventions: improve one core page, correct one entity inconsistency and pursue one relevant citation opportunity. In week four, rerun the same prompts, document changes and decide whether automation will save enough analyst time.
Frequently asked questions
Can Google Search Console show all AI brand mentions?
No. Search Console provides performance data for Google Search surfaces; it is not a universal transcript or mention log for independent AI assistants. Use it alongside answer-level monitoring and analytics.
How often should prompts be checked?
Weekly is enough for many starting teams. High-volatility news, reputation or product-launch topics may require more frequent checks. Consistency matters more than maximum frequency.
How many competitors should be tracked?
Start with three to five direct alternatives plus any unexpected brands that repeatedly appear. A huge competitor list makes the analysis noisy.
Dageno is the research and insights team at Dageno AI, publishing industry reports and expert analysis on AI Search Visibility, Generative Engine Optimization (GEO), and AI-powered search discovery.