Best Nudge Alternative: 5 AI Shopping & GEO Tools (2026) | Dageno AI

Dageno • Jul 28, 2026
Updated by
Updated on Sep 11, 2026
The hardest part of generative engine optimization for beginners is not adding schema or writing “AI-friendly” copy. It is building a repeatable system for choosing prompts, collecting variable answers, diagnosing source gaps and connecting visibility to business outcomes.
AI answers vary by model, search activation, location, language and time. A single screenshot is a sample, not a rank. Use a stable prompt set and repeated measurements.
A brand can be named without a link, cited without being recommended, or recommended negatively. Track mention, citation, recommendation context and sentiment separately.
Branded prompts inflate performance. Build a balanced set covering category discovery, problems, comparisons, alternatives, implementation and validation. Weight prompts by business value.
Pricing, integrations, security, geographic support and limitations are often scattered or outdated. Create clear canonical pages with dates, evidence and consistent terminology.
AI systems may cite reviews, forums, media and community discussions. Map the domains actually used for your prompt set before publishing more owned content.
Important facts may be hidden behind client-side rendering, blocked crawlers or conflicting canonical tags. Check rendered HTML, status codes, robots directives, internal links and sitemaps. OpenAI says inclusion requires allowing OAI-SearchBot; see its publisher guidance.
Generated answers are noisy. Annotate every content or PR change and wait for repeated movement. A higher visibility score does not prove revenue impact.
SEO, content, product marketing, PR and analytics each control part of the evidence. Assign one owner to the prompt baseline and one owner to every action.
Start with 30 prompts, three competitors, two priority AI platforms and one market. Capture raw answers weekly for four weeks. Categorize every gap as content, source, technical, product-fact or reputation. Ship only the three highest-value fixes, then remeasure the same prompts.
| Week | Work | Deliverable |
|---|---|---|
| 1 | Prompt research and baseline | Raw answers and scorecard |
| 2 | Citation and competitor diagnosis | Prioritized gap map |
| 3 | Content, source and technical fixes | Published change log |
| 4 | Repeated measurement | Before/after decision report |
Avoid invented industry benchmarks. Your first four weeks establish the baseline appropriate to your market.
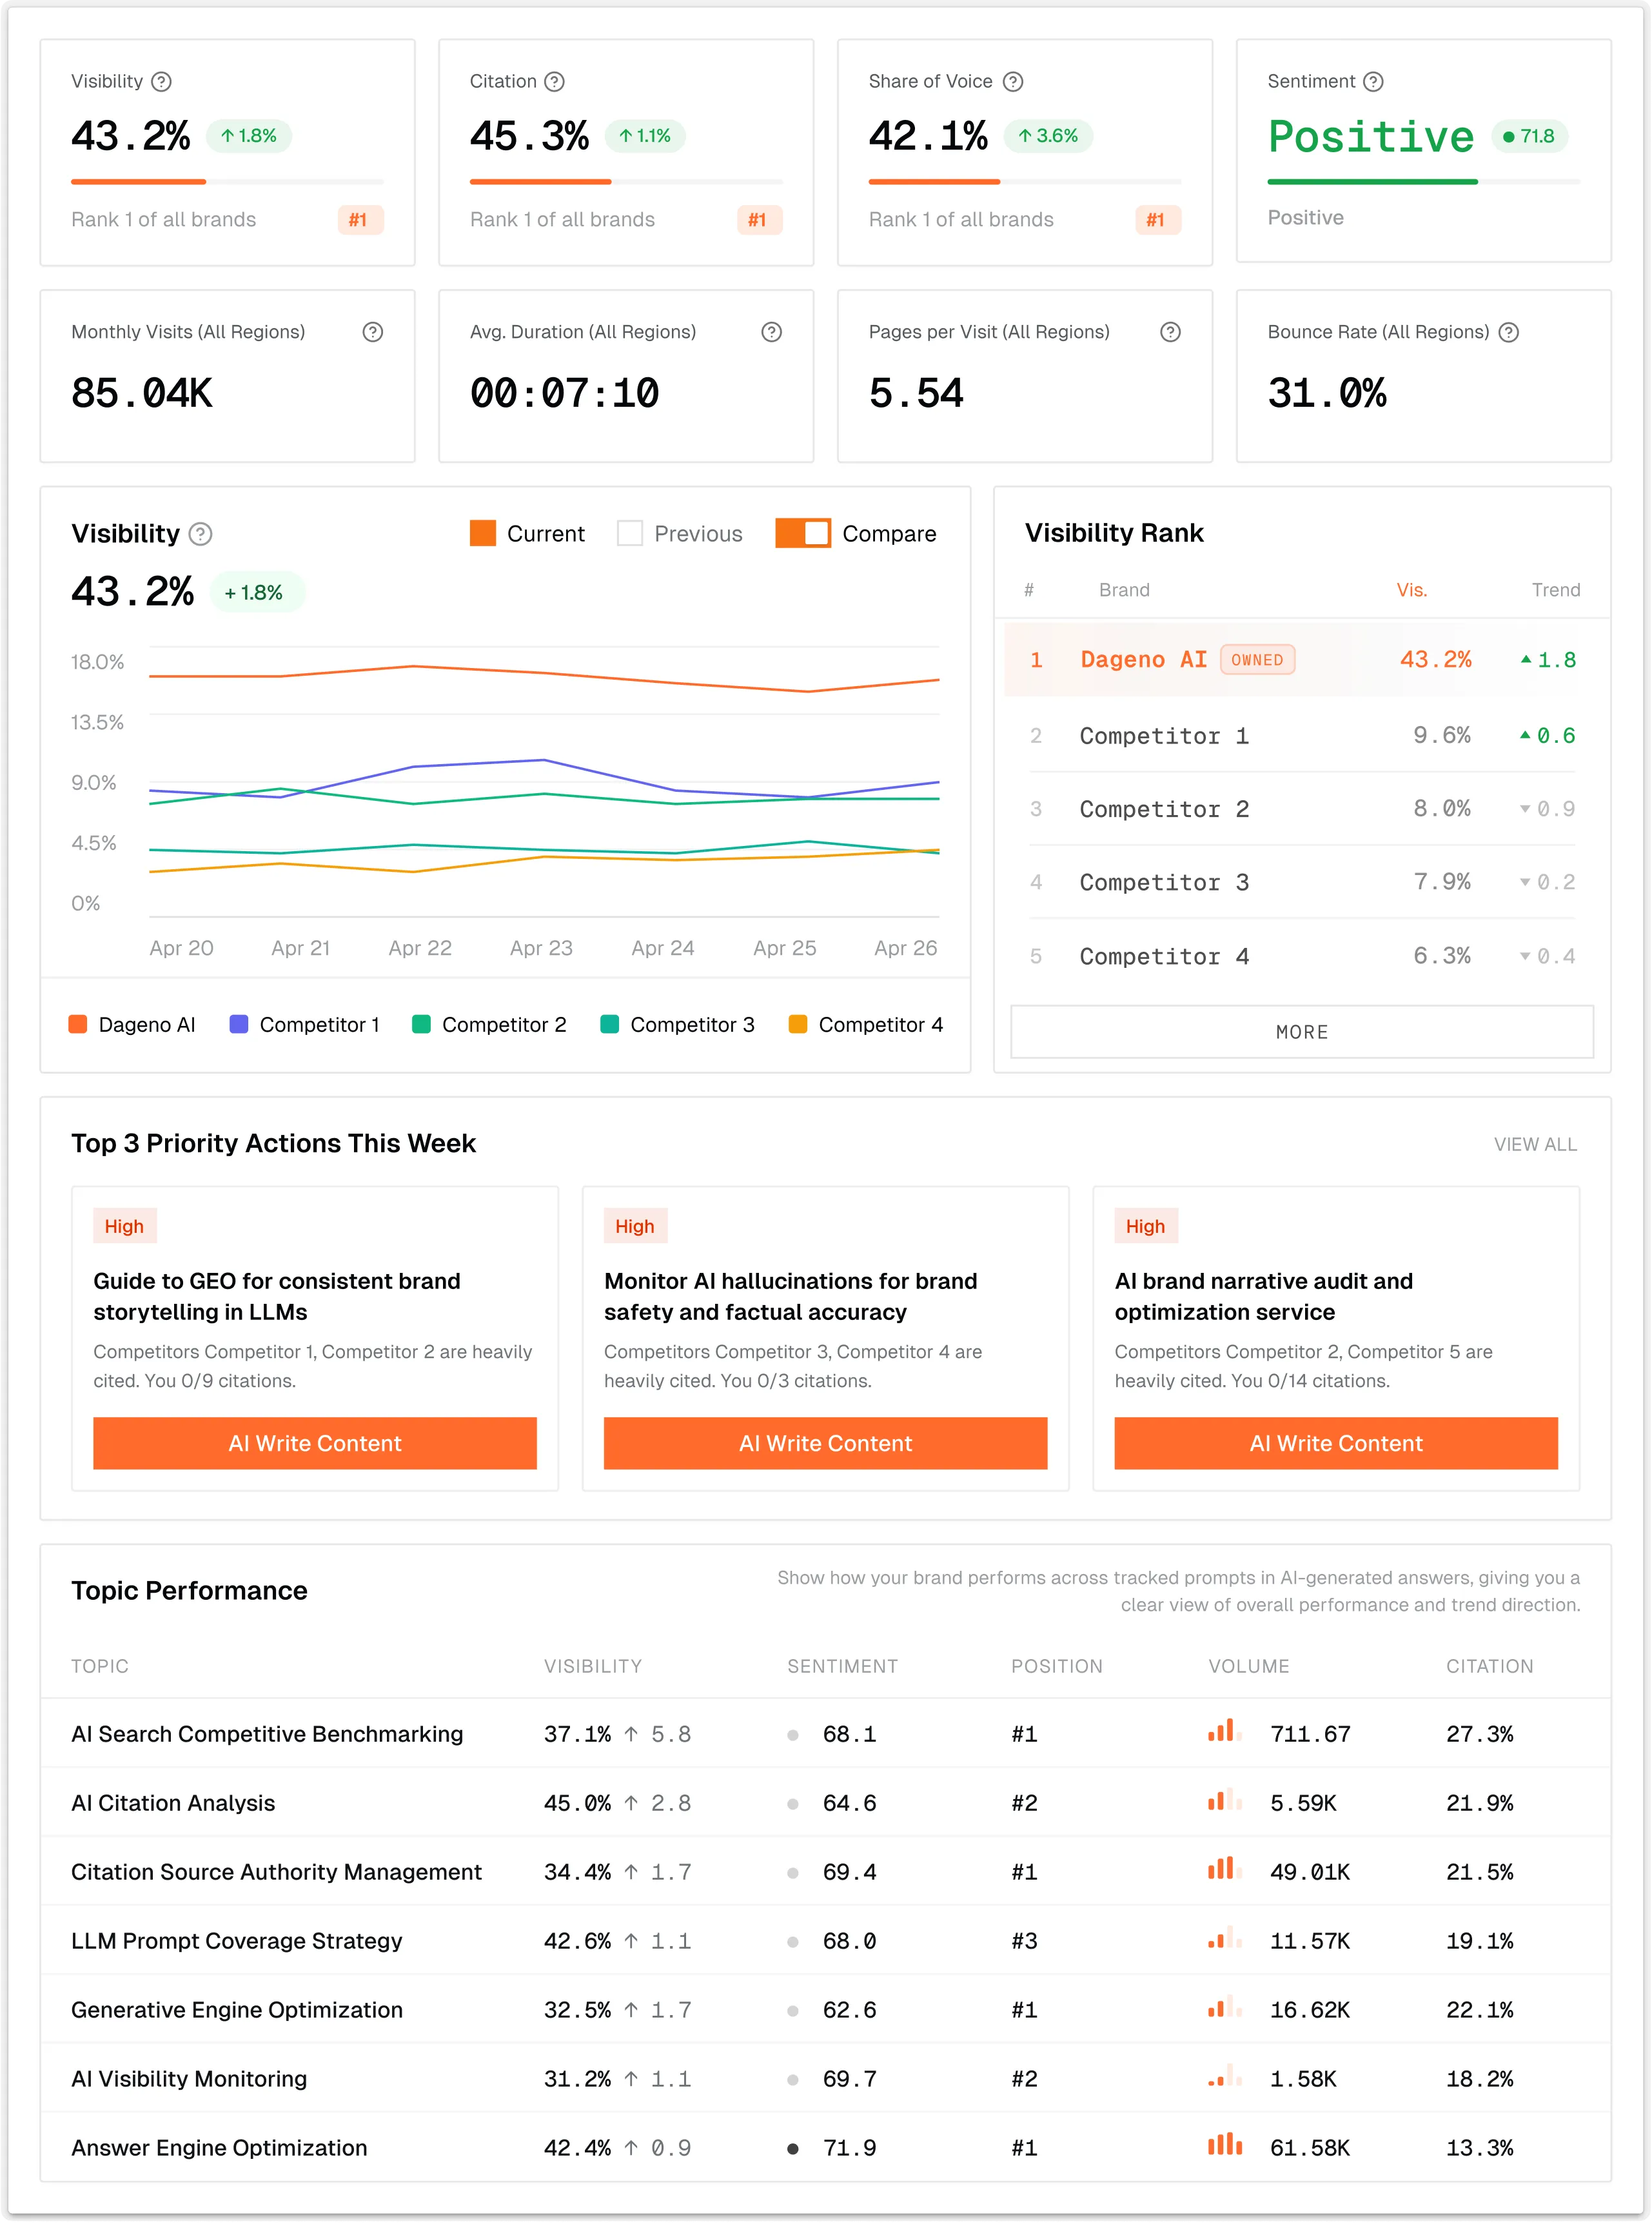
Dageno connects prompt monitoring, competitor answers, citation sources and content opportunities. It helps a beginner move from “we are missing” to a specific page, source or message that needs attention, while retaining the raw evidence behind the metric.
Ready to dominate AI search?
Get started - it's free! >Do not create hundreds of generic pages, add unsupported FAQ markup, buy low-quality mentions or report one answer as a trend. Do not block search crawlers while expecting live-search citations. Most importantly, do not optimize only for AI visibility: content still needs to help people make a decision.
Continue with the GEO metrics framework, prompt coverage analysis and LLM citation strategy.
Four weeks is enough to establish a working baseline, but not to promise causal impact. Continue repeated tracking for stable categories.
No. Valid structured data can clarify entities, but it cannot compensate for inaccessible, thin or unsupported content.
They can provide demand, crawl and traffic data. Dedicated answer monitoring is needed for mentions, citations, narrative and prompt-level competitor visibility.
Dageno is the research and insights team at Dageno AI, publishing industry reports and expert analysis on AI Search Visibility, Generative Engine Optimization (GEO), and AI-powered search discovery.
Read full bio