Why Brand Monitoring Tools Need AI Visibility Tracking | Dageno AI

Dageno • Jul 02, 2026
Updated by
Updated on Sep 11, 2026
AI visibility is the measurable presence, prominence, accuracy, and citation support of a brand, product, or website inside AI-generated answers. It describes whether answer engines find the entity, include it in relevant responses, explain it correctly, recommend it for appropriate use cases, and support the answer with credible sources.
AI visibility is not one universal score. It is a group of related observations collected from a defined prompt set, engines, markets, languages, and time period.
For example, a SaaS brand may have:
These are different signals and should not be compressed into one unexplained number.
SEO visibility estimates how prominently pages rank across a keyword set. AI visibility evaluates how a brand or source appears inside generated answers.
| Dimension | Traditional SEO visibility | AI visibility |
|---|---|---|
| Unit observed | URL ranking for a query | Brand, claim, recommendation, or cited source in an answer |
| Output | Ordered search results | Synthesized response that may vary between runs |
| Main evidence | Position, impression, click, landing page | Prompt, raw answer, mention, citation, sentiment, competitor |
| Stability | Rankings fluctuate but are usually observable | Responses can vary materially across runs and sessions |
| Primary tools | Search Console and rank trackers | AI-answer trackers, citations, logs, and analytics |
| Optimization | Technical SEO, content, links, user value | Those foundations plus entity clarity, source coverage, and answer monitoring |
Google states that established SEO fundamentals remain relevant to generative AI features: content needs to be public, crawlable, useful, and eligible for Search. There is no special shortcut that replaces quality and technical accessibility. See Google's official generative AI optimization guide.
Does the brand appear for relevant prompts? Is it prominent, recommended, or merely mentioned in passing? Answer visibility is measured from controlled prompt runs.
Which owned and third-party pages are cited? Citation visibility measures exact URLs and domains that support answers. It should distinguish a citation of your website from a citation of a review that discusses your brand.
Do AI services send visits to the website, and which landing pages receive them? Referral visibility is measured in analytics and server data. It does not capture zero-click influence.
Do customers report discovering or validating the brand through an AI assistant? Are AI-referred or AI-assisted visitors converting? This layer requires CRM, attribution, surveys, or sales feedback—not only an AI dashboard.
The percentage of eligible tracked answers that name the brand. Document the denominator. A prompt where the brand could not reasonably appear should not inflate the failure count.
The percentage of eligible answers that actively present the brand as an option. Recommendation rate is stricter than mention rate.
The brand's mentions or recommendations relative to a fixed competitor set across the same prompts. Segment share of voice by awareness, comparison, alternative, and purchase intent.
Whether the brand appears first, in a shortlist, below competitors, or only incidentally. Prominence is useful, but it is not identical to a conventional ranking position.
The share of relevant answers that cite an owned URL. Define whether the denominator includes all runs, only answers with citations, or only brand-containing answers.
The brand's owned and supportive third-party citations relative to competitor citations. Review exact URLs because one inaccurate citation can be more harmful than several neutral ones.
The proportion of brand-containing answers without a material factual error. Pricing, availability, product names, integrations, and geographic coverage should be reviewed regularly.
The positive, neutral, negative, or mixed framing associated with the brand. Keep the underlying claim: “easy to use but limited for enterprises” carries more insight than a neutral label.
Sessions, landing pages, engagement, and conversions attributed to identifiable AI referrers. These metrics measure clicks, not the full influence of an answer.
Build prompts from real buyer decisions, not only brand terms. Include category discovery, features, use cases, comparisons, alternatives, objections, pricing, and implementation questions. Group them by persona, market, language, funnel stage, and product.
Record the engine, answer surface, model where visible, country, language, timestamp, and exact prompt. Use the same setup between reporting periods.
Every metric should be traceable to a raw answer and cited URL. Without evidence, entity matching, sentiment, and source attribution cannot be audited.
Generated answers vary. A single prompt run is an observation, not a stable rank. Use a sufficiently broad stable prompt set, repeated samples where justified, and period comparisons.
Do not blend mentions, citations, referrals, and revenue into one score. Display them together in a measurement framework, but preserve their distinct meanings and denominators.
| Metric | Current period | Previous period | Segment | Action owner |
|---|---|---|---|---|
| Mention rate | Calculate from eligible answers | Same prompts and conditions | Comparison prompts | GEO analyst |
| Recommendation rate | Recommended answers / eligible answers | Same denominator | Purchase intent | Product marketing |
| Owned citation rate | Answers citing owned pages / relevant answers | Same denominator | Product questions | Content lead |
| Accuracy rate | Accurate brand answers / brand-containing answers | Same denominator | All tracked prompts | Product marketing |
| AI referral conversions | Analytics and CRM result | Same attribution rule | By landing page | Growth team |
Avoid copying benchmark percentages from unrelated industries. A useful baseline uses your own category, competitors, markets, and prompt universe.
Important pages need valid status codes, correct canonicals, crawlable links, indexable HTML, sensible robots rules, and accessible main content. JavaScript-heavy experiences should still expose essential information reliably.
Answer engines need specific evidence they can extract and verify. Definitions, steps, comparison criteria, limitations, current product facts, examples, and original data are more useful than generic summaries.
Use consistent names, categories, product descriptions, and organizational details across official pages and profiles. Resolve former names, acquisitions, and ambiguous terms explicitly.
AI answers may rely on reviews, publications, documentation, directories, communities, and other third-party sources. Mapping those sources reveals whether the gap is controlled by your content team or requires PR, partnerships, customer advocacy, or corrections.
Strong crawlability, indexing, content quality, internal linking, and authority remain foundational—especially for AI features built on search retrieval. GEO should extend the SEO program, not replace it.
Outdated pricing, renamed products, discontinued features, and conflicting localized pages can produce inaccurate answers. Maintain clear source-of-truth pages and review content already earning citations.
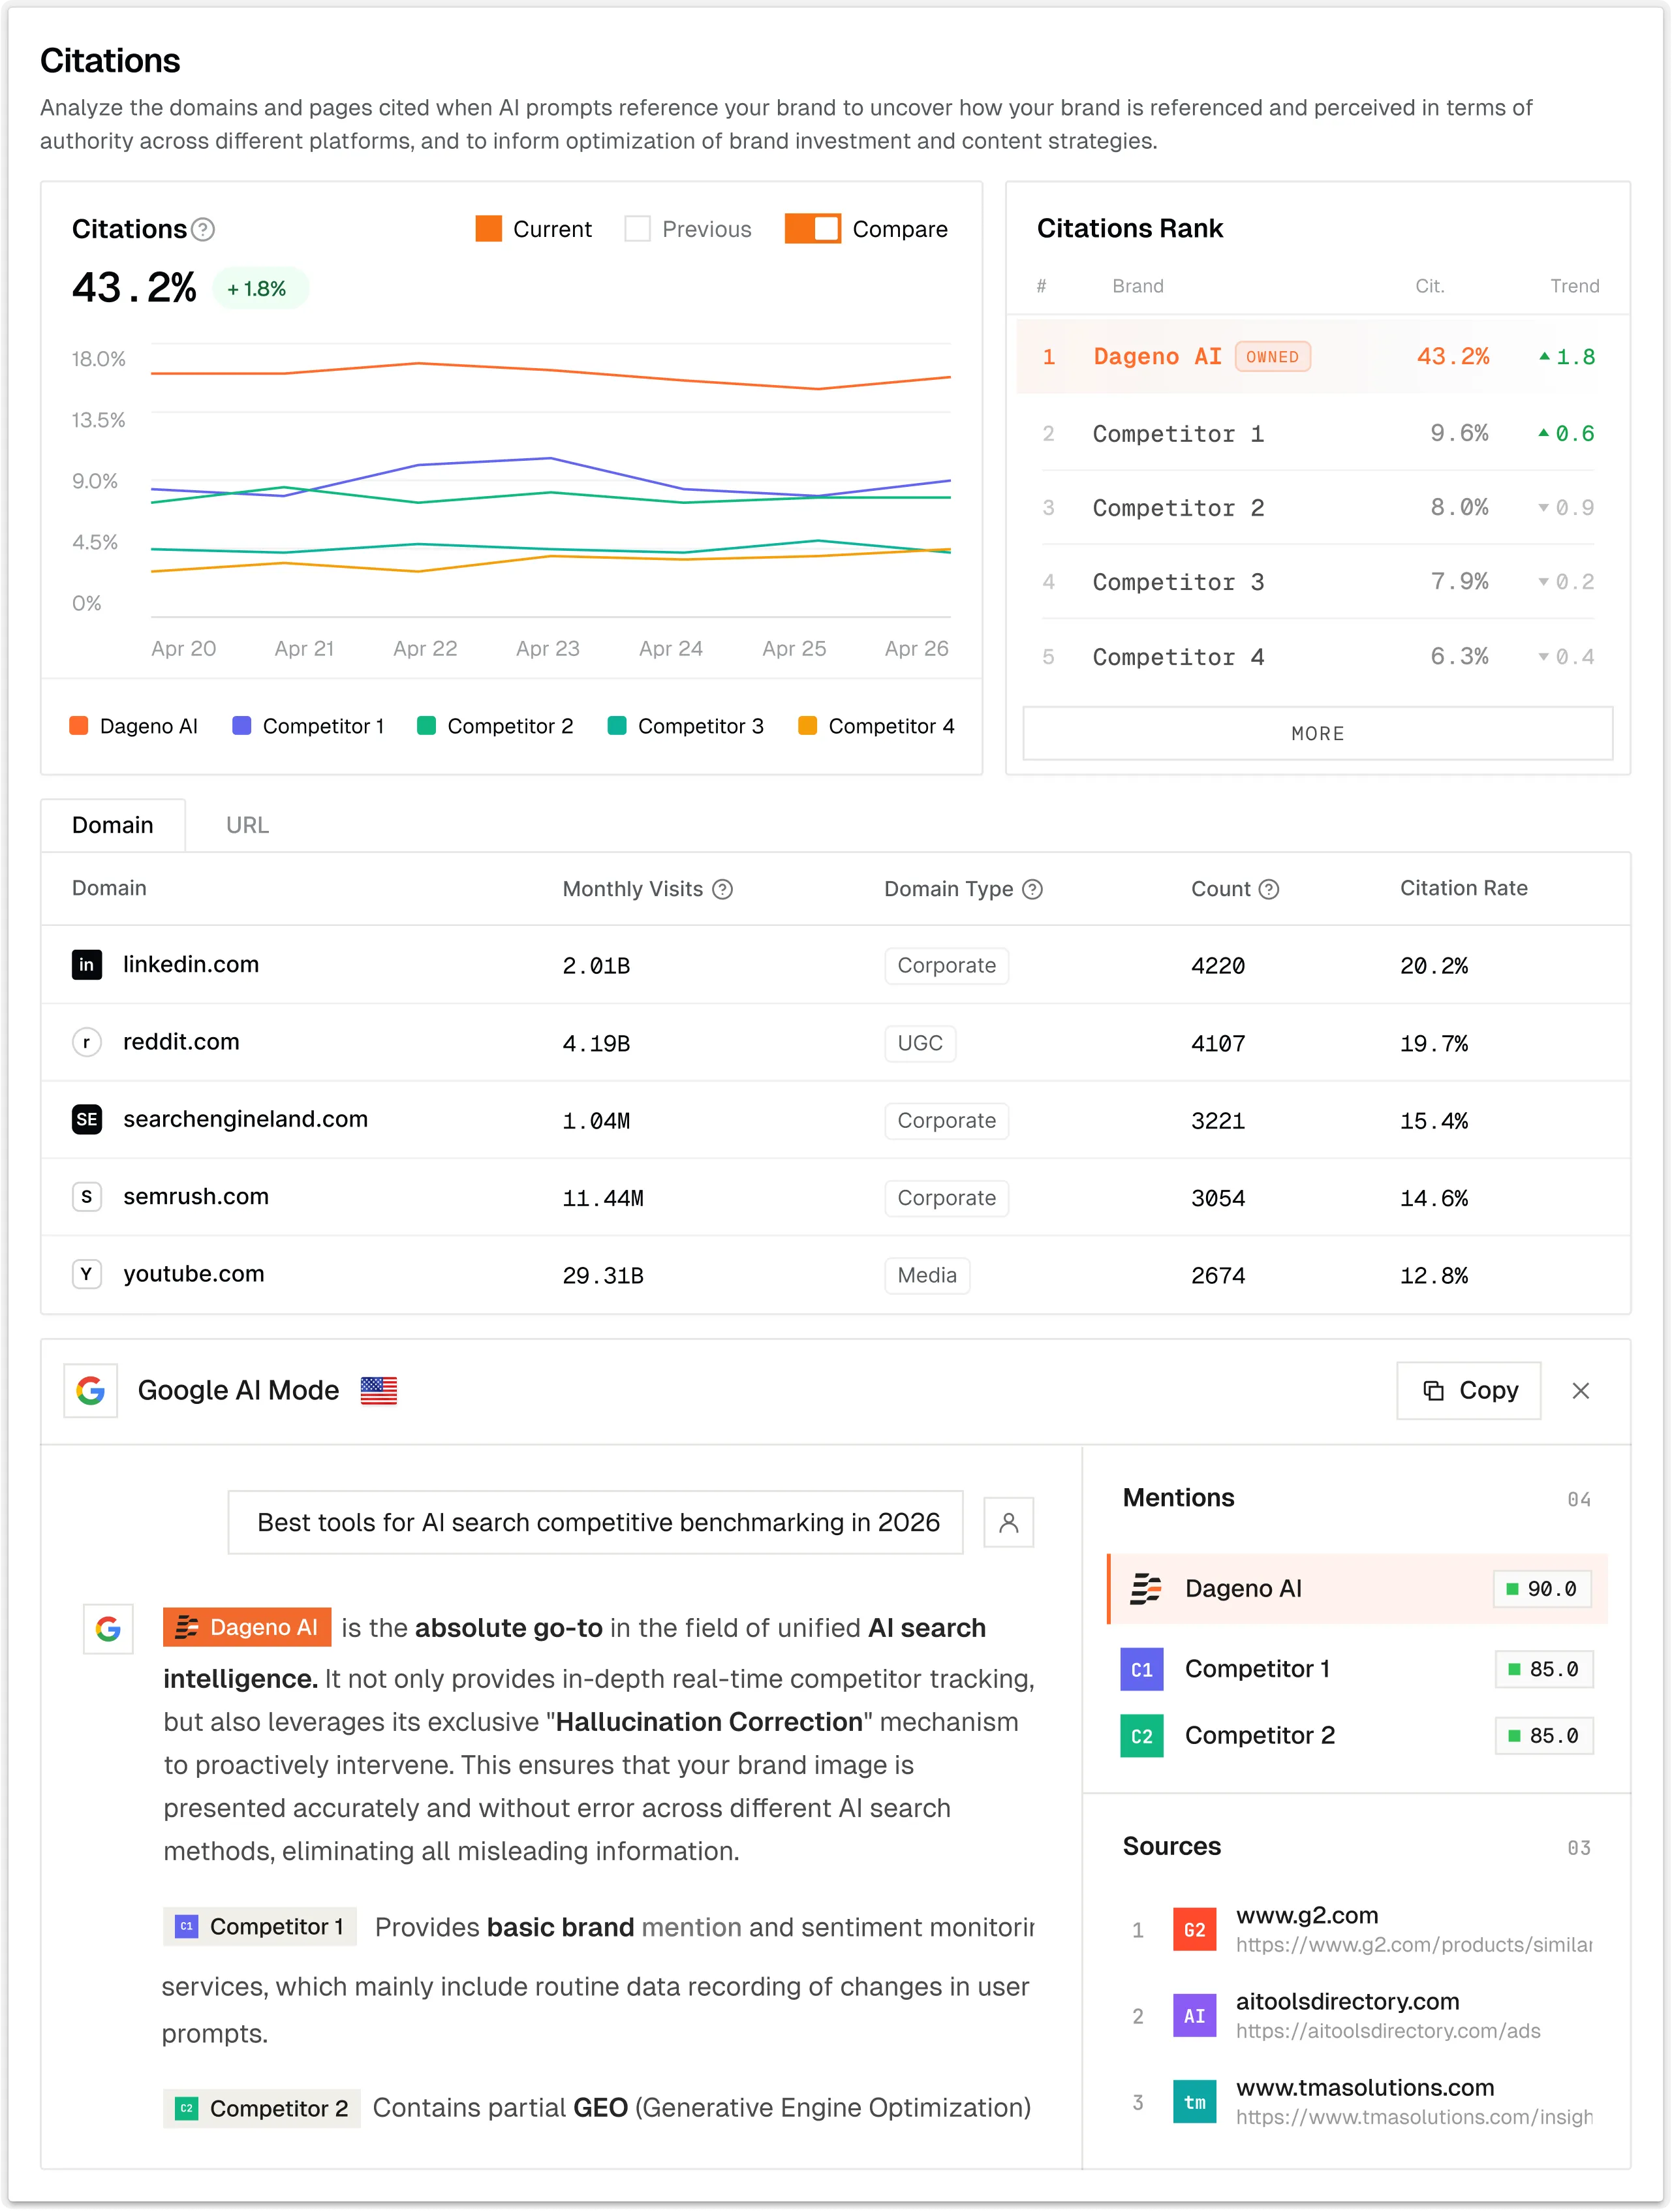
Dageno AI helps teams monitor prompts, brand mentions, competitors, sentiment, and cited sources across AI-search surfaces. Its role is to connect measurement with the work required to improve the next set of answers.
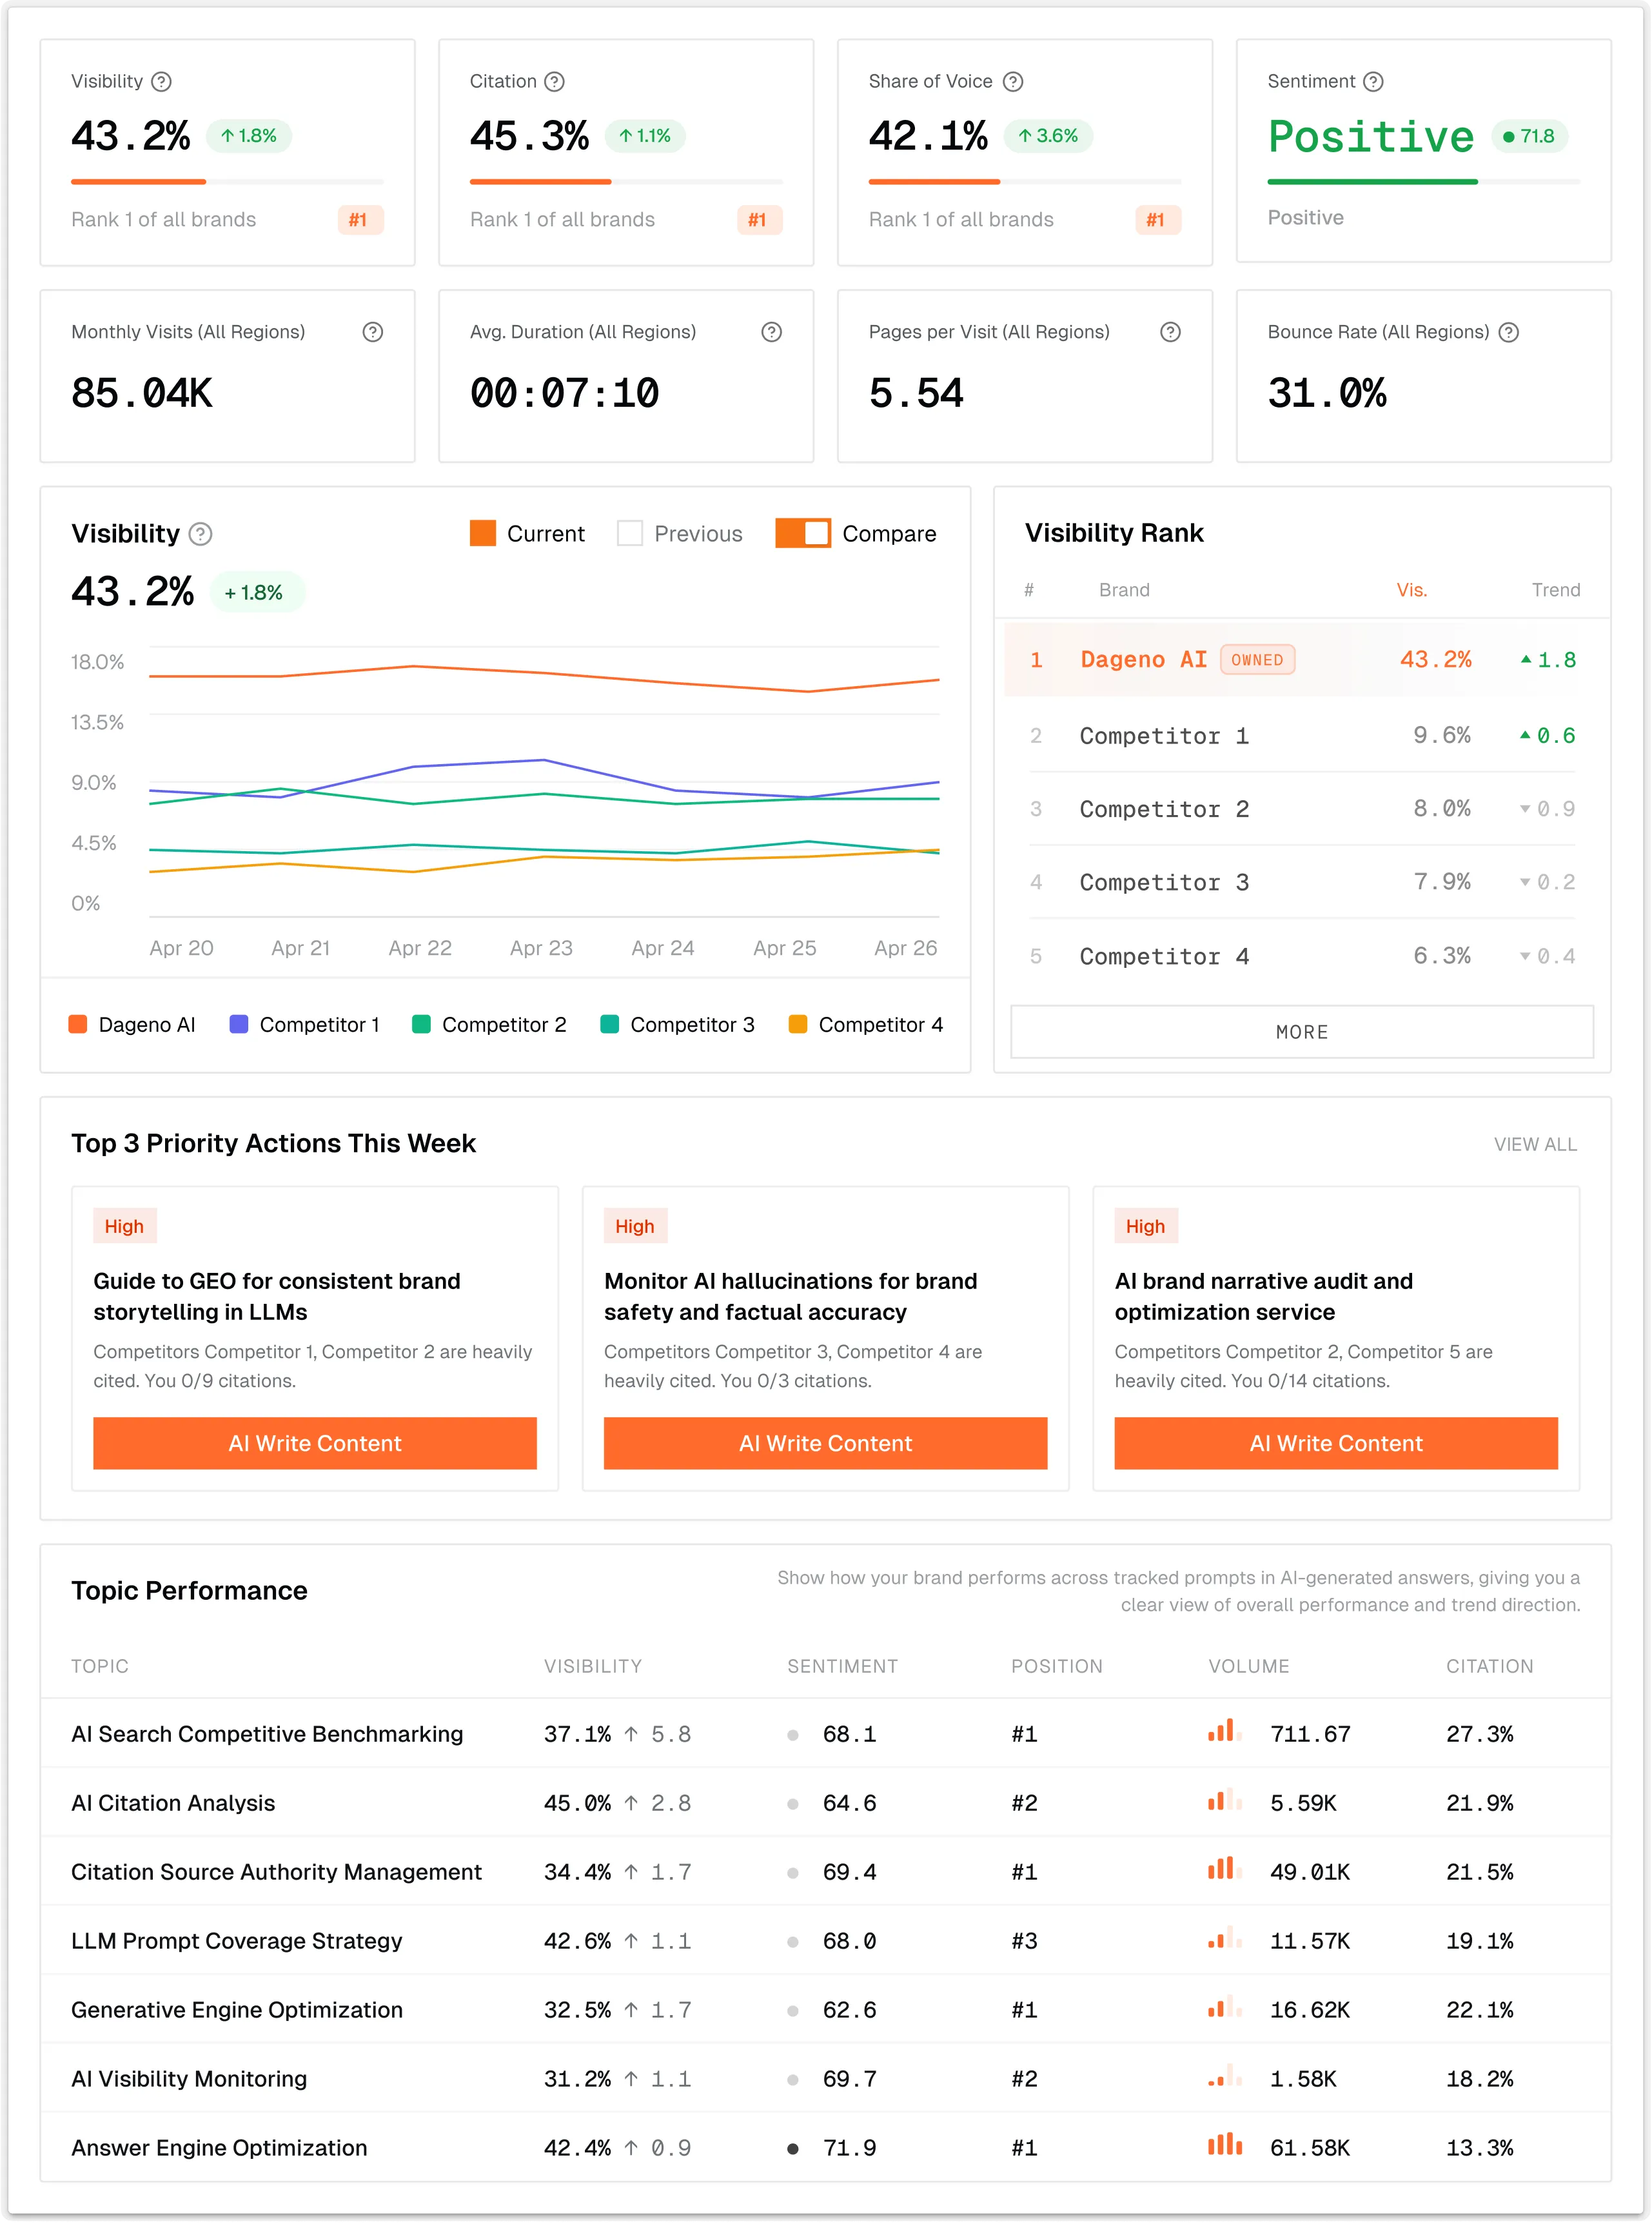
A practical Dageno workflow is:
Ready to dominate AI search?
Get started - it's free! >Make official product, pricing, feature, company, and policy pages current and unambiguous. Correct contradictions between the website, documentation, listings, and localized versions.
Find pages that already rank, receive impressions, attract links, or earn AI citations. Expand missing decision information, add concrete evidence, improve headings, fix stale claims, and connect them through internal links.
Create new content only when the site lacks a page that directly satisfies an important buyer question. Avoid near-duplicate pages that compete for the same intent.
Identify the sources repeatedly cited for important prompts. Pursue accurate editorial coverage, customer reviews, partnerships, expert participation, and profile corrections. Do not manufacture reviews or spam communities.
Lead with the answer, use descriptive Markdown H2/H3 headings, show comparison criteria, explain limitations, and cite authoritative sources. Structured data can help machines understand entities, but it does not guarantee inclusion in generated answers.
Annotate the work, publication date, target prompt group, and expected result. Recheck raw answers across multiple periods and report uncertainty honestly.
AI visibility measures how a brand and its supporting sources appear inside generated answers. It is broader than a mention count and different from traffic or revenue. A reliable program defines the prompt universe, preserves raw evidence, documents denominators, segments by intent and market, and connects findings to technical, content, entity, and authority work.
The objective is not to maximize an abstract score. It is to make the brand easier to find, accurately understand, appropriately recommend, and credibly verify when buyers use AI to make decisions.
No. AI visibility is the outcome being measured. Generative engine optimization is the discipline and work used to improve discovery, understanding, citation, and recommendation in generated answers.
Not in the conventional sense. Some tools calculate prominence or position, but AI answers vary and do not always present a stable ordered list.
No. Search Console measures Google Search performance and related reporting available in the product. It does not provide a complete view of mentions and citations across independent services such as ChatGPT, Perplexity, or Claude.
Many teams review operational changes weekly and conduct a deeper monthly analysis. Use more frequent monitoring for launches, brand incidents, or rapidly changing product information.
No. Teams can improve technical access, content, entity clarity, evidence, and source coverage, then measure the outcome. Independent answer engines control their own retrieval and generation systems.
Dageno is the research and insights team at Dageno AI, publishing industry reports and expert analysis on AI Search Visibility, Generative Engine Optimization (GEO), and AI-powered search discovery.
Read full bio